TL;DR

Get the latest gadgets delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Thorsten Meyer AI has published a 2026 comparison arguing that the Mac-versus-GPU-tower choice for local LLMs is mainly a tradeoff between quiet capacity and faster throughput. The report says GPU towers are faster on models that fit in VRAM, while Apple Silicon machines can run larger quantized models with far less heat and noise.
Thorsten Meyer AI has published a 2026 comparison of Apple Silicon Macs and GPU towers for local LLM workloads, arguing that the buying decision is less about one machine being better overall and more about whether users prioritize quiet operation, larger unified memory or faster token generation on models that fit in GPU VRAM.
The analysis says GPU towers and Apple Silicon systems optimize for different limits. A tower built around an RTX 5090 is described as bandwidth-first, with roughly 1,792 GB/s of memory bandwidth and 24GB to 32GB of VRAM per consumer card. Thorsten Meyer AI says that gives the tower a clear speed advantage on models that fit inside that memory envelope.
Apple Silicon is described as capacity-first. The source material cites the Mac Studio M3 Ultra at about 819 GB/s of memory bandwidth, but with unified memory configurations reaching up to 512GB. According to the analysis, that allows a Mac to load 70B-class or larger quantized models that would not fit on a single consumer GPU, though token generation is slower.
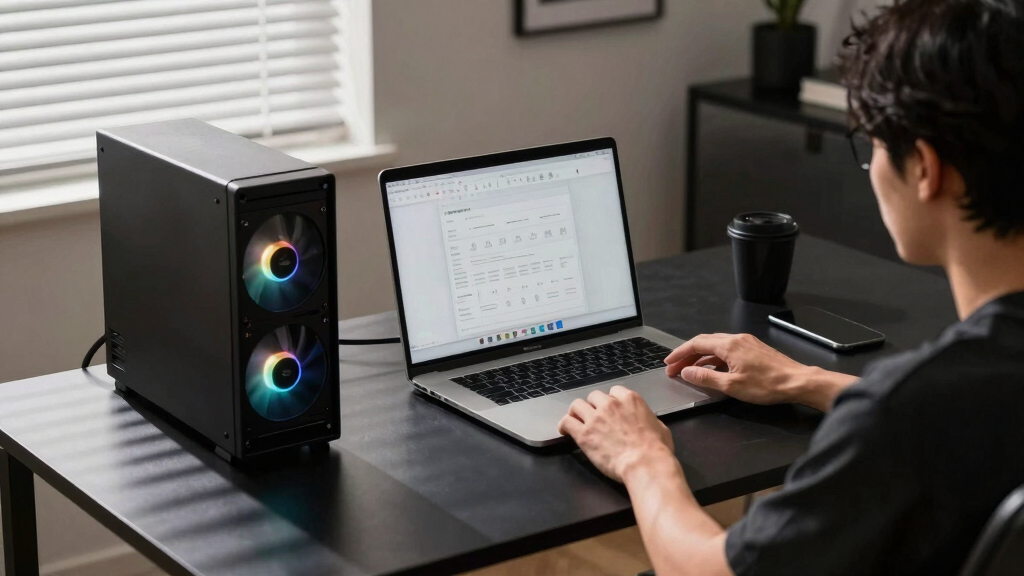
The heat-and-noise comparison is central to the report. The source says a single RTX 5090 can draw 575W and that a dual-GPU tower can exceed 800W, while a Mac Studio operates at a fraction of that power draw. The article frames the GPU tower as a system that can be quieted through undervolting, cooling, case airflow, fan tuning and placement, while describing the Mac as near-silent by design.
Why It Matters
The report matters for developers, researchers and hobbyists running LLMs locally because the hardware choice affects daily work, not only benchmark results. A high-end tower can produce faster output on workloads that fit in VRAM, but it can also add heat, fan noise, power use and placement constraints to a home office or studio.
For users working with larger local models, the analysis points to a different constraint: whether the model can be loaded at all. Apple’s unified memory architecture may make larger quantized models practical on a desktop Mac, even when the same model is outside the memory limit of a single consumer GPU. That makes the Mac a quieter but slower option for some local inference use cases.
Apple Silicon Mac Studio M3 Ultra
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Background
The comparison is presented as the capstone to Thorsten Meyer AI’s series on reducing heat and noise in high-power AI workstations. Earlier parts of the series focused on making GPU towers more livable through tuning and component choices. This installment asks whether some users should avoid much of that heat and noise by choosing Apple Silicon instead.
The source material also points to a hybrid setup as a common answer: keeping a quiet Mac at the desk for interactive work and larger-memory inference, while placing a headless GPU tower in another room for throughput jobs, CUDA workflows and fine-tuning. That arrangement keeps tower noise away from the user while preserving access to GPU performance when needed.
“The real Mac-versus-tower decision for local AI is not only about tokens per second.”
— Thorsten Meyer AI
“A GPU tower is a high-bandwidth furnace you spend five levers learning to quiet.”
— Thorsten Meyer AI
“Apple Silicon is near-silent by design — but asks for different tradeoffs.”
— Thorsten Meyer AI
As an affiliate, we earn on qualifying purchases.
What Remains Unclear
The comparison gives ballpark figures and says token rates vary by model, quantization and workload. It does not provide a single benchmark table covering every Mac, GPU, quantization format or local inference engine. Pricing is also not fixed in the source material, and real-world value will depend on live component costs, memory configuration, software support and whether a user needs CUDA.
quiet high-performance AI workstation
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What’s Next
Readers comparing systems should test the actual models they plan to run, check whether those models fit within available VRAM or unified memory, and weigh speed against desk-side noise, heat and power use. The next practical step is likely a workload-specific comparison: smaller models that fit in 32GB VRAM favor the tower for speed, while larger quantized models may favor a high-memory Mac or a hybrid setup.
As an affiliate, we earn on qualifying purchases.
Key Questions
Is a GPU tower faster than a Mac for local LLMs?
According to Thorsten Meyer AI, yes, when the model fits in GPU VRAM. The cited RTX 5090 bandwidth figure is roughly 1,792 GB/s, compared with about 819 GB/s for the Mac Studio M3 Ultra.
Why would someone choose a Mac for local LLMs?
The main reason in the source material is memory capacity and quiet operation. A high-memory Apple Silicon system can load larger quantized models and run near-silently compared with a high-power GPU tower.
Can two consumer GPUs combine their VRAM for one model?
The source says consumer GPU VRAM does not simply pool into one larger memory space. That means two cards can help some workloads, but they do not automatically create one combined memory pool for a single model.
What setup does the report suggest for users who want both quiet and speed?
Thorsten Meyer AI points to a hybrid arrangement: a quiet Mac at the desk for interactive work and larger-memory models, plus a headless GPU tower in another room for high-throughput jobs, fine-tuning and CUDA workloads.
Source: Thorsten Meyer AI
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.