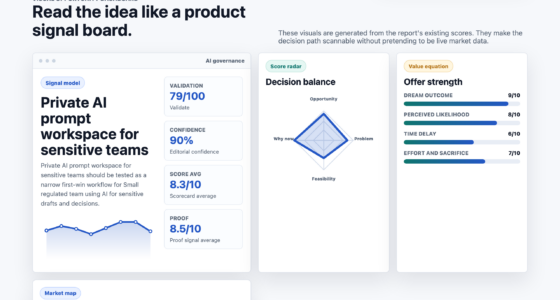
📊 Full opportunity report: Discover How LFM2.5-VL-3B Enhances Vision For Edge AI Systems on ThorstenMeyerAI.com — validation score, market gap, and execution plan.

Get the latest gadgets delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
TL;DR
Developers have announced LFM2.5-VL-3B, a 3.1-billion-parameter model designed for local hardware that improves vision tasks like screen understanding and object grounding. While benchmark results are promising, independent verification is pending. The model aims to enable faster, private AI applications on edge devices, as detailed in the original analysis.
The developers of LFM2.5-VL-3B have introduced a 3.1-billion-parameter vision-language model optimized for local hardware, capable of processing screens, documents, and multiple images in real time. This development aims to improve privacy, reduce latency, and support high-volume inference for edge AI applications.
The LFM2.5-VL-3B model combines a SigLIP2 400M NaFlex vision encoder with a pretrained backbone used in earlier text models, trained on approximately 34 trillion tokens and four times more vision data than previous models. Learn more about this development. It supports a 128,000-token vocabulary with expanded coverage for non-Latin scripts. According to the developers, the model was fine-tuned through supervised learning, knowledge distillation, and reinforcement learning, with a focus on producing direct answers for faster responses.
In developer evaluations, performance benchmarks showed an average score of 69.4 across vision tasks, significantly higher than the 57.2 of its predecessor. For a detailed review, see this internal analysis. Specific results include 91.1 on DocVQA and 87.9 on RefCOCO grounding. These results are based on internal testing with non-reasoning prompts, and independent verification remains pending.
The model can run fully on local hardware, with deployment sizes fitting in about 3 GB of memory. Performance varies depending on hardware, with speeds reaching 228 tokens/sec on high-end GPUs and much lower on mobile devices. These metrics are preliminary, and real-world performance may differ based on device configuration and workload.
Implications for Privacy and Real-Time Edge AI
The ability to run this powerful vision-language model locally could significantly impact applications such as assistive technology, industrial automation, and privacy-sensitive systems. By processing data directly on devices, it reduces the need for data transmission to the cloud, potentially enhancing privacy and decreasing latency. However, the actual privacy benefits depend on implementation details, which are not yet fully disclosed.
Moreover, the model’s support for multi-image analysis and tool calling broadens the scope of real-time applications, from on-screen object recognition to complex document understanding. This could enable more responsive, autonomous systems but raises questions about safety and reliability, especially in safety-critical environments.
edge AI vision processing hardware
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Advances in On-Device Vision Models and Prior Developments
Recent years have seen increasing interest in edge AI models capable of processing visual and textual data locally, driven by privacy concerns and latency needs. Previous models like LFM2-VL-3B laid groundwork for combining vision and language, but often relied on cloud processing for high performance. The new LFM2.5-VL-3B builds on these efforts, emphasizing local deployment and enhanced multi-modal understanding.
Prior benchmarks and models have demonstrated the feasibility of on-device AI, but often faced limitations in speed, accuracy, or multi-image interpretation. The developers’ claims of improved performance and broader support for non-Latin scripts mark a step forward, though independent verification is still awaited to confirm these advances.
“Our most capable vision-language model you can run on your own hardware.”
— LFM2.5-VL-3B developers
As an affiliate, we earn on qualifying purchases.
Pending Independent Validation and Real-World Testing
It remains unclear how independent benchmarks will compare to developer-reported results. Details on hardware configurations, safety, and handling of poor-quality inputs are not yet available. The actual performance and reliability in diverse real-world scenarios are still under assessment.
vision-language model for edge devices
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Expected Independent Evaluations and Broader Deployment
Next steps include independent testing on various hardware platforms, including consumer devices and industrial systems. Additional details on performance metrics, safety, and robustness are anticipated as the model sees wider adoption. Developers may also release updates to improve accuracy and safety features based on early feedback.
high-performance GPU for AI inference
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Questions
What is LFM2.5-VL-3B?
LFM2.5-VL-3B is a 3.1-billion-parameter vision-language model designed for local hardware, capable of understanding screens, documents, and multiple images in real time.
Can the model run entirely offline?
Yes, according to the developers, the model can operate fully on-device, fitting into about 3 GB of memory, though actual performance depends on hardware specifics.
What improvements does LFM2.5-VL-3B offer over previous models?
The new model enhances screen understanding, object grounding, multi-image analysis, and function calling, with broader support for non-Latin scripts and faster inference capabilities.
Has the performance been independently verified?
No, the current results are developer-reported benchmarks. Independent testing is needed to confirm these claims across different environments.
What are potential applications of this model?
Uses include document extraction, interface assistance, visual question answering, and on-screen object identification, especially in privacy-sensitive and real-time contexts.
Source: ThorstenMeyerAI.com
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.